Updated 24 October 2026
Sharding and partitioning
Horizontal partitioning strategies (range, hash, directory), consistent hashing, choosing a shard key, hot shards, cross-shard queries, and resharding without downtime.
Try it yourself, in a playground:Consistent hashing on a hash ringChoosing a shard keyHot keysRendezvous hashingLocal vs global indexes
Partitioning splits a dataset so that each piece lives on a different node. It is how you scale writes and storage past one machine. Sharding usually means the same thing applied to a database. The design questions are always the same three: how do you decide which node holds a key, what do you do when a key or node is hot, and how do you add nodes later without downtime.
Why partition
One node has a limit on disk, memory, write throughput and connections. Read replicas scale reads, not writes or storage. When the write rate exceeds what a single primary does (order of 10 k/s for relational databases) or the data no longer fits, you partition. Partition later rather than earlier: every cross-partition operation (joins, transactions, secondary-index queries) becomes harder.
Strategies
Range partitioning. Each shard owns a contiguous key range: users A to F on shard 1. Range scans are efficient (all of one range on one node) and the mapping is easy to reason about. The risk is hot ranges: time-ordered keys put all new writes on the last shard, and alphabetical keys are uneven. Used by HBase, Bigtable, Spanner, and by hand in many relational setups.
Hash partitioning. Shard = hash(key) mod N (or a consistent-hash ring). Spreads keys evenly regardless of their distribution. The cost is that range queries across keys touch every shard, and adding a node with naive modulo remaps almost every key. Used by Cassandra, DynamoDB, Redis Cluster, and most caches.
Directory (lookup) partitioning. A separate service holds an explicit map from key (or tenant) to shard. Fully flexible, lets you move one hot tenant to its own shard, and supports non-uniform shards. The lookup service must be highly available and cached everywhere. Used for multi-tenant SaaS and by systems like Vitess.
Most systems combine them: hash on a partition key to pick a shard, then range-order within the shard by a sort key (Cassandra's partition and clustering keys, DynamoDB's partition and sort keys).
Consistent hashing
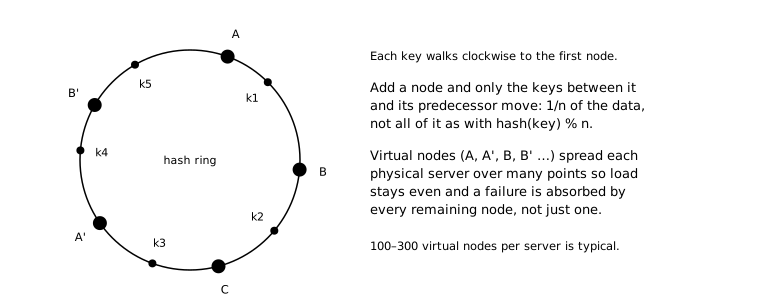
With hash mod N, going from 10 to 11 nodes changes the shard of roughly 10/11 of all keys, which means a near-total cache miss or data migration. Consistent hashing fixes this. Place each node at several points (virtual nodes, typically 100 to 200 each) on a ring of hash values; a key belongs to the first node clockwise from its hash. Adding a node takes over slices from many neighbours, moving only about 1/N of the keys; removing one hands its slices to the next nodes. Virtual nodes keep the load even when nodes have different capacities and avoid the case where one node inherits an entire neighbour's range.
Used by Cassandra, DynamoDB, Riak, and by load balancers and cache clients for sticky routing. Say "consistent hashing with virtual nodes" and the interviewer will usually move on; be ready to explain why virtual nodes matter if they do not.
Choosing the shard key
The shard key decides the whole system's behaviour, and changing it later is a migration. It must:
- Spread load evenly. High cardinality and uniform distribution. User id is usually good; country, status or date are bad.
- Keep together what is queried together. All of one user's data on one shard means "everything for user X" is one query. All of one channel's messages together means history is one range scan.
- Support the dominant access pattern. If every query starts with "for this tenant", shard by tenant.
Typical choices: user id for user-centric products, tenant id for B2B, channel or conversation id for messaging, entity id for catalogues. A composite key (tenant_id + user_id) lets you route by tenant while keeping ranges manageable.
Hot shards and hot keys
Even with a good key, some keys are hot: a celebrity user, a 50 k-member channel, a viral product. One shard saturates while the rest idle. Techniques, roughly in order of preference:
- Cache the hot key in front of the store; most hot keys are read-hot.
- Salt the key. Append a random suffix from a small range (
key#0…key#9), spreading writes over ten partitions; reads fan out to all ten and merge. Good for counters and append streams. - Bucket by time.
channel_id + dayso one busy channel's history spreads over many partitions and old buckets go cold. - Split the shard. Range-partitioned stores split a hot range automatically (HBase, Spanner); hash-based ones need a resharding step.
- Isolate the tenant. With a directory, move the whale to a dedicated shard.
Cross-shard operations
Anything not keyed by the shard key gets expensive.
- Secondary index queries ("orders by status = pending") must scatter to every shard and gather. Keep them rare, or maintain a global secondary index (DynamoDB GSI, or your own table keyed by the secondary attribute) that is updated asynchronously.
- Joins across shards do not exist. Denormalise: store the data you need together, and accept duplicated writes.
- Transactions across shards need two-phase commit or a saga. See distributed transactions. Design the key so that the transactions you need stay within one shard (all of an order's line items with the order).
- Unique constraints across shards (unique email) need either a dedicated lookup shard keyed by the attribute or a global index with a write-before-insert check.
Resharding
You will need more shards. The plan should exist before you need it.
- Pre-split. Create far more logical partitions than physical nodes (1024 slots on 8 nodes). Growing means moving whole slots, which is a copy, not a re-hash. Redis Cluster, Kafka, and many sharded MySQL setups work this way.
- Double writes with backfill. Write to old and new layouts, backfill the new from the old, verify, then cut reads over, then stop writing to the old. This is how large migrations are done in practice and takes weeks; say so.
- Consistent hashing makes adding a node move 1/N of the keys, which the store does online (Cassandra streams token ranges to the new node).
Routing
Something has to send a request to the right shard: the client library (Cassandra drivers are token-aware), a proxy (Vitess, ProxySQL, Redis Cluster's MOVED redirects), or a lookup service for directory partitioning. Say where the routing lives and how it learns about topology changes (gossip, a config store like ZooKeeper or etcd).
In the interview
"Shard the messages table by channel id with a hash, clustered by message id, using consistent hashing with virtual nodes so adding nodes moves only 1/N of the data. Large channels are the hot-partition risk, so I bucket the partition key by day. Queries by user across channels need a separate table keyed by user id, written asynchronously from the message stream." That covers key, strategy, hot spot, and cross-shard query in three sentences.
Secondary indexes across shards
Once data is partitioned by one key, every query on a different field becomes a problem. Two answers, and you should name which one you are using:
- Local (document-partitioned) index. Each shard indexes its own rows. Writes are cheap and local; reads must scatter to every shard and gather. Fine when the query is rare or the shard count is small.
- Global (term-partitioned) index. A separate index partitioned by the indexed field, so a read touches one shard. Reads are cheap; writes now touch two partitions and are no longer atomic, so the index is updated asynchronously and is eventually consistent.
The practical pattern in large systems: keep the primary store partitioned by the write key, and maintain global secondary access paths as derived data, a search index or a second table keyed by the other field, populated from the event stream.
Multi-tenant partitioning
When the data is naturally per customer, shard by tenant and life gets simpler: every query is scoped, cross-shard joins mostly disappear, and a noisy tenant is isolated. The two wrinkles are size skew (one enterprise customer is 1 000× the median) and the smallest tenants wasting a shard.
The usual arrangement: small tenants share pooled shards, large tenants get dedicated ones, and a tenant→shard mapping table in a small strongly consistent store lets you move a tenant without changing the hash. Moving a tenant is then a documented operation (copy, catch up from the log, flip the mapping, drain) rather than a resharding project.
Checklist
- The shard key, and the access pattern it optimises.
- The queries that now require a scatter-gather, and their rate.
- Hot-key and hot-shard handling.
- How the number of shards changes, and what happens to in-flight requests.
- Where the routing map lives and who updates it.
Questions people ask
What is sharding in system design?
Sharding splits a database's data so that each piece, or shard, lives on a different node, which is how writes and storage scale past one machine. Read replicas scale reads, not writes or storage, so you shard when the write rate exceeds what one primary handles (on the order of 10 k/s for relational databases) or the data no longer fits. Shard later rather than earlier, because joins, transactions and secondary-index queries across shards become harder.
Sharding vs partitioning: what is the difference?
There is little difference: partitioning splits a dataset so that each piece lives on a different node, and sharding usually means the same thing applied to a database. Both are how you scale writes and storage past one machine. Either way the design questions are the same three: how to decide which node holds a key, what to do when a key or node is hot, and how to add nodes later without downtime.
Range vs hash partitioning: what is the difference?
Range partitioning gives each shard a contiguous key range, so range scans are efficient, while hash partitioning sets shard = hash(key) mod N, which spreads keys evenly regardless of their distribution. Range risks hot ranges, because time-ordered keys put every new write on the last shard, and hash makes range queries across keys touch every shard. Most systems combine them: hash on a partition key to pick the shard, then order by a sort key within it, as Cassandra and DynamoDB do.
How do you choose a shard key?
Choose a shard key with high cardinality and uniform distribution that keeps together what is queried together and matches the dominant access pattern. It matters because the key decides the whole system's behaviour, and changing it later is a migration. User id is usually good and country, status or date are bad; typical choices are user id for user-centric products, tenant id for B2B, and channel or conversation id for messaging.
How does consistent hashing help with sharding?
Consistent hashing lets a sharded store add a node while moving only about 1/N of the keys, whereas with hash mod N going from 10 to 11 nodes changes the shard of roughly 10/11 of all keys. Each node sits at several points on a ring of hash values (virtual nodes, typically 100 to 200 each), and a key belongs to the first node clockwise from its hash. Virtual nodes keep load even when nodes have different capacities.
What is a sharded counter?
A sharded counter splits one hot counter across several keys by appending a random suffix from a small range (key#0 … key#9), so writes spread over ten partitions instead of one. Reads fan out to all ten and merge the results. It is needed because even with a good shard key, some keys are hot, such as a celebrity user or a viral product, and one shard saturates while the rest idle.