Updated 24 October 2026
Rate limiting and resilience
Token bucket, leaky bucket, fixed and sliding windows, distributed rate limiters, plus the resilience toolkit: timeouts, retries with backoff and jitter, circuit breakers, bulkheads, load shedding and graceful degradation.
Try it yourself, in a playground:Token bucket and other rate limitersThe circuit breaker patternExponential backoff and jitterLoad sheddingBulkhead patternDeadline propagationDistributed rate limitingShuffle shardingFair queuingRetry stormsWebhook deliveryAdaptive concurrency limits
Systems fail in two ways under load: someone sends too much, or a dependency slows down and the slowness spreads. Rate limiting handles the first; the resilience patterns handle the second. Interviewers ask about both when they say "what happens if the recommendation service is down" or "how do you stop one customer from taking down the API".
Rate limiting algorithms
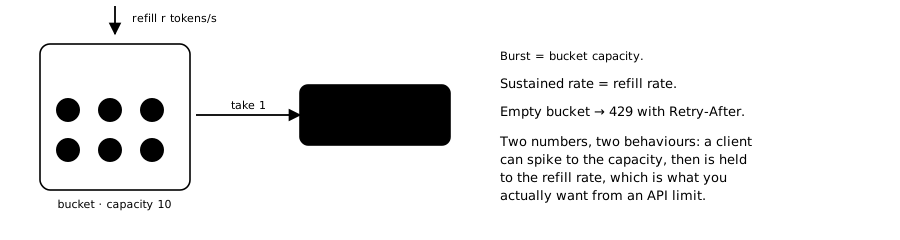
Token bucket. A bucket holds up to B tokens and refills at r per second. Each request takes a token; no token, reject. Allows bursts up to B while enforcing an average of r. Two numbers, O(1) state (count and last refill time), and the semantics people want. This is the default answer; it is what most cloud APIs use.
Leaky bucket. Requests enter a queue that drains at a fixed rate. Smooths output to exactly r, no bursts. Used when the downstream must see a constant rate (a third party with a hard limit).
Fixed window. Count requests per calendar minute; reset at the boundary. Trivial, but allows 2× the limit across a boundary (all of minute 1's quota at 0:59, all of minute 2's at 1:00).
Sliding window log. Store a timestamp per request; count those within the last window. Exact, but memory grows with the rate.
Sliding window counter. Weighted combination of the current and previous fixed-window counts. Approximate, O(1) memory, no boundary burst. A good choice when you need windows rather than buckets.
Where the counters live
A single server can keep buckets in memory. Behind a load balancer, each server sees 1/N of a client's traffic, so per-server limits are N× too generous. Options:
- Centralised in Redis. Key per client (
rl:{client}), a Lua script that does refill-and-take atomically, TTL on the key. One round trip (~0.5 ms) per request. Redis handles hundreds of thousands of checks per second; shard by client key beyond that. - Local with sync. Each server enforces locally and periodically reconciles with a shared count. Cheaper and tolerant of Redis being down, at the cost of accuracy.
- At the edge. CDNs and API gateways offer rate limiting per IP or token before requests reach you.
Say what happens when the limiter's store is unavailable: fail open (allow, log, alert) for most products, because a rate limiter outage should not become an API outage; fail closed for abuse-sensitive endpoints like login.
Limits and keys
Key by API key or user for authenticated traffic, by IP for anonymous (with care: NATs and mobile carriers share IPs). Apply different limits per endpoint class (reads vs writes vs expensive queries) and tier (free vs paid). Return 429 Too Many Requests with Retry-After and X-RateLimit-Limit/Remaining/Reset headers so clients back off intelligently. Distinguish rate limits (requests per second, protects capacity) from quotas (requests per month, a billing concept).
Timeouts
Every network call needs a timeout, and the timeout should be set from the caller's budget, not the callee's typical latency. A request with a 500 ms budget that makes three sequential calls cannot give each 500 ms. Propagate deadlines (gRPC does this natively) so a call that cannot finish in time is cancelled rather than completed uselessly. Missing timeouts are the most common cause of cascading failure: threads pile up waiting on a slow dependency until the caller itself runs out.
Retries with backoff and jitter
Retry only idempotent operations and only on transient errors (timeouts, 503, connection reset), never on 4xx. Use exponential backoff (100 ms, 200, 400, …) capped at a maximum, with jitter (randomise each delay) so that a thousand clients retrying after the same failure do not retry at the same instant and cause a second failure. Cap the retry count (2 or 3) and make the total retry budget a fraction of traffic (e.g. retries are at most 10 % of requests), because retries against an overloaded service are the mechanism by which a partial outage becomes a total one. Retry at one layer, not at every layer, or three layers of three retries become 27 attempts.
Circuit breakers
A circuit breaker watches calls to a dependency. When the failure rate crosses a threshold (say 50 % over 10 seconds), it opens: calls fail immediately without touching the dependency, giving it time to recover and freeing the caller's threads. After a cool-down it goes half-open, lets a few trial calls through, and closes if they succeed. Combine with a fallback: cached data, a default, or a degraded response. Libraries: Resilience4j, Polly, Envoy's outlier detection. Say "circuit breaker with a fallback to the cached recommendations" and the dependency-outage question is answered.
Bulkheads
Isolate resources so one failing dependency cannot exhaust everything. Separate thread pools or connection pools per downstream; separate queues per tenant or priority; separate deployments for critical and best-effort paths. Named after ship compartments: a leak floods one, not the ship. The concrete interview form: "the payment path has its own pool and its own instances so a slow search backend cannot starve checkout".
Load shedding and backpressure
When overloaded, do less work rather than doing all of it slowly. Reject early (at the gateway, based on queue length or CPU) with 503 and Retry-After; drop low-priority traffic first (background syncs before user actions; free tier before paid); return cheaper responses (skip personalisation). Bounded queues everywhere: an unbounded queue turns overload into memory exhaustion and a crash. Backpressure means the slowness propagates to the producer so it slows down (TCP does this; so does a bounded queue that blocks or rejects).
Graceful degradation
Decide in advance what the system does without each dependency. Feed without ranking: chronological. Search without spell-check: exact. Checkout without the fraud service: allow up to a limit and review later, or block above it. Product pages without reviews: hide the section. Writing this list is what "design for failure" means concretely, and it is a strong staff-level signal.
Idempotency and the retry storm
Retries are only safe because operations are idempotent. See distributed transactions and idempotency. The classic incident: a payment service slows, clients time out and retry, the service processes both the original and the retry, customers are double-charged, and the retries triple the load so the service falls over. Idempotency keys prevent the first; retry budgets and circuit breakers prevent the second.
In the interview
"Token bucket per API key in Redis via a Lua script, 100 requests/s with a burst of 200, fail open if Redis is down. Internally every call has a deadline derived from the request budget, retries at most twice with exponential backoff and jitter on idempotent calls only, and a circuit breaker per dependency with a fallback. Critical paths have their own connection pools. Under overload the gateway sheds background traffic first."
Client-side limits
The cheapest request is the one that is never sent. Well-behaved clients (your own mobile app, your SDK) should carry the limits with them: a local token bucket, respect for Retry-After, exponential backoff with jitter, request coalescing for identical in-flight calls, and a circuit breaker of their own. Server-side limits then exist to handle clients you do not control.
This matters for a specific failure: a mobile app that retries immediately on failure turns a 30-second outage into a self-inflicted denial of service at recovery. Jittered backoff on the client is what prevents the thundering herd when you come back up.
Testing that the resilience works
Resilience that has never been exercised does not exist. Name at least one of these:
- Load testing to a known breaking point, so you know the capacity number rather than guessing it.
- Fault injection: add latency or errors to a dependency in a staging environment, or to a small percentage of production traffic, and check the circuit breaker opens and the degraded path is what you expect.
- Game days / chaos experiments: kill an instance, an availability zone, or a dependency on purpose, during working hours, with an owner watching.
- Dependency drills: every quarter, verify that the fallback behaviour for each critical dependency still matches what the runbook claims.
Checklist
- Algorithm, limits and keys, plus what a limited client receives.
- Where counters live and what happens when that store is down.
- Timeouts on every outbound call, and the retry policy with jitter.
- Circuit breakers on the dependencies that can be slow.
- The degraded experience for each dependency, described in user terms.
- How any of this has been tested.
Questions people ask
What is rate limiting?
Rate limiting caps how many requests a client can send, so that one customer cannot take down the API. The default algorithm is a token bucket: the bucket holds up to B tokens and refills at r per second, and each request takes one token, which allows bursts up to B while enforcing an average of r. A limited client should receive 429 Too Many Requests with a Retry-After header so it backs off.
What is the difference between a token bucket and a leaky bucket?
A token bucket allows bursts up to its capacity while enforcing an average rate, whereas a leaky bucket queues requests and drains them at a fixed rate, so the output is smooth with no bursts. The token bucket needs only two numbers and O(1) state (a count and the last refill time), and it is the default answer and what most cloud APIs use. A leaky bucket fits when the downstream must see a constant rate, such as a third party with a hard limit.
What is exponential backoff with jitter?
Exponential backoff grows the wait between retries exponentially (100 ms, 200, 400 and so on) up to a cap, and jitter randomises each delay. Without jitter, a thousand clients retrying after the same failure retry at the same instant and cause a second failure. Retry only idempotent operations on transient errors such as timeouts, 503 or a connection reset, cap retries at 2 or 3, and retry at one layer only, because three layers of three retries become 27 attempts.
What is a circuit breaker in system design?
A circuit breaker watches calls to a dependency and opens when the failure rate crosses a threshold, so calls fail immediately without touching the dependency. That gives the dependency time to recover and frees the caller's threads. A threshold might be 50 % failures over 10 seconds; after a cool-down the breaker goes half-open, lets a few trial calls through, and closes if they succeed. Pair it with a fallback such as cached data, a default or a degraded response.
Why does every network call need a timeout?
Without timeouts, threads pile up waiting on a slow dependency until the caller itself runs out, which makes missing timeouts the most common cause of cascading failure. Set each timeout from the caller's budget, not the callee's typical latency: a request with a 500 ms budget that makes three sequential calls cannot give each call 500 ms. Propagate deadlines so that a call which cannot finish in time is cancelled rather than completed uselessly.
Should a rate limiter fail open or fail closed?
Most products should fail open (allow, log and alert) when the rate limiter's store is unavailable, because a rate limiter outage should not become an API outage. Abuse-sensitive endpoints such as login should fail closed instead. A typical distributed setup keeps a token bucket per API key in Redis, refilled and taken atomically by a Lua script in one round trip of about 0.5 ms, and fails open if Redis is down.