Updated 24 October 2026
Caching
Where to cache (browser, CDN, application, database), cache-aside vs write-through vs write-back, eviction policies, invalidation, hot keys, thundering herds and cache stampedes.
Try it yourself, in a playground:LRU, LFU and FIFO cache evictionCache stampedeFan-out on write vs readCDN caching and hit ratioTrie and typeaheadCache write policiesHot keysHTTP cachingCache sizing
Caching is storing the result of expensive work close to where it is needed so the next request skips the work. It is the first tool for read scaling and the first thing an interviewer expects when the read rate is high. It is also the source of the most subtle bugs in distributed systems, which is why "how do you invalidate it" is the follow-up every time.
Where to cache
From the user inward, each layer catches a share of requests so the next layer sees fewer.
| Layer | What it holds | Controlled by |
|---|---|---|
| Browser | static assets, API responses | Cache-Control, ETag |
| CDN edge | static assets, public pages, sometimes API responses | Cache-Control, s-maxage, surrogate keys |
| Application cache (Redis, Memcached) | query results, computed objects, sessions, counters | your code |
| Local in-process cache | the very hottest keys, config | your code, tiny TTL |
| Database cache | pages and index blocks in memory | the database |
An interview answer usually names two: CDN for static and public content, Redis for the hot working set of the application. Add a small in-process cache only when you are talking about a hot-key problem.
Read strategies
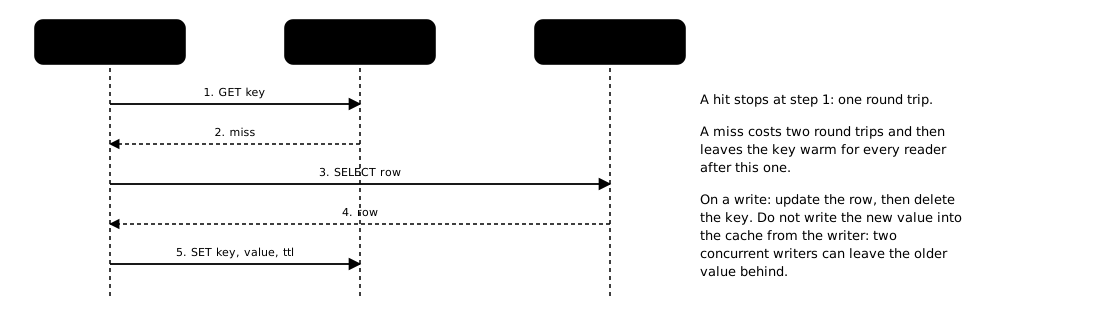
Cache-aside (lazy loading). The application checks the cache; on a miss it reads the database, writes the result to the cache, and returns it. Simple, only caches what is actually read, and a cache failure degrades to the database. The costs: the first read of every key is a miss, and stale data lives in the cache until the TTL expires or someone invalidates it. This is the default answer.
Read-through. The cache itself loads from the database on a miss. Same behaviour as cache-aside but the logic lives in the cache library or proxy. Cleaner code, less control.
Write strategies
Write-around. Write to the database only and let the cache entry expire or be invalidated. Combined with cache-aside, this is the common pattern: write to the DB, delete the cache key. The next read repopulates it.
Write-through. Write to the cache and the database synchronously. Reads after a write are always fresh, at the cost of write latency and caching data that may never be read.
Write-back (write-behind). Write to the cache, acknowledge, and flush to the database later in batches. Very fast writes and coalescing of hot updates (a counter incremented 10 k times becomes one database write), but a cache failure loses unflushed writes. Used for counters, view tallies, and other data where loss of a few seconds is acceptable.
Invalidation
There are only three real strategies and every system uses a mix.
- TTL. Every entry expires after N seconds. Simple and bounds staleness; choose the TTL by how stale the data may be. Add jitter (random ±10 %) so entries written together do not all expire together.
- Explicit invalidation on write. Delete or update the key when the source changes. Precise but requires every writer to know every cache key that depends on the data, which decays as the system grows.
- Event-driven. Writers publish change events (or the database's change stream does); a consumer invalidates affected keys. Decoupled, works across services, and eventually consistent by a few hundred milliseconds.
The dangerous race: reader misses, reads old value from DB; writer updates DB and deletes cache key; reader writes old value into cache. Now the cache is stale until TTL. Mitigations: short TTLs as a backstop, delete-then-write-then-delete-again ("double delete" with a small delay), or versioned keys where the cache stores (value, version) and a write with a lower version is ignored.
Eviction
When the cache is full, something goes. LRU (least recently used) is the default and right for most workloads. LFU (least frequently used) protects long-lived popular keys from being pushed out by a scan of one-time reads; Redis offers an approximate LFU. FIFO and random are used when the metadata cost of LRU matters. Size the cache from the working set: in a Zipfian workload, the top 1 % of keys receive most of the traffic, so a cache holding a few percent of the data gives a 90 %+ hit rate. See the estimation guide.
Hot keys and thundering herds
A hot key is a single key receiving a large fraction of traffic: a celebrity's profile, the home page config, a viral link. Redis handles ~100 k to 1 M ops/s on one node, and a single key lives on one node, so one key can saturate a shard while the others idle. Fixes: replicate the key across N shards with a suffix (key#1 … key#N) and read a random one; add a small in-process cache with a 1 to 5 s TTL on every application server; serve the value from the CDN.
A thundering herd or cache stampede happens when a hot key expires and thousands of concurrent requests all miss and all hit the database at once. Fixes: request coalescing (a per-key lock or singleflight so one request recomputes and the rest wait), stale-while-revalidate (serve the expired value while one request refreshes in the background), and probabilistic early expiration (each reader refreshes with a small probability before the TTL, spreading the refresh).
A cold cache after a restart or a new region is the same problem for every key at once. Warm it from a snapshot or from a list of the top keys before taking traffic, and rate limit the database while it fills.
Consistency: what to promise
A cache is by definition a copy, so the honest promise is "eventually consistent within the TTL, and immediately consistent for the writer's own session if we invalidate on write". Say which data cannot be cached at all: balances, inventory counts at checkout, anything the user is about to act on where a stale read causes a wrong action. For those, read from the primary or from a cache that is updated in the same transaction (rare and expensive).
Redis versus Memcached
Memcached is a simple multithreaded key-value cache; it is slightly faster per node for plain get/set and scales by adding nodes with client-side hashing. Redis is single-threaded per core but has data structures (lists, sorted sets, hashes, sets), pub/sub, Lua scripts, persistence and replication, and a built-in cluster mode. Choose Redis when you need any structure (leaderboards, rate limiting, queues) or persistence; choose Memcached for a pure large object cache. In an interview, Redis is the safe default and nobody will object.
Sizing example
100 M items, 1 KB each, Zipfian reads at 50 k/s. Caching the hottest 5 % (5 M items, 5 GB) yields roughly a 95 % hit rate, so the database sees 2.5 k/s. Three Redis nodes of 8 GB each with replicas cover it with room to grow. The point of saying this out loud is that it turns "add a cache" into a design with numbers.
Negative caching
A key that does not exist is still a lookup. If misses are cheap to produce (a scanner probing random ids, a client polling for a record that has not been created yet) every miss reaches the database. Cache the absence too: store a small tombstone with a short TTL (5–30 s), or put a Bloom filter in front so "definitely not present" is answered without a lookup at all. The short TTL matters: a negative entry that outlives the creation of the real record produces a user-visible "not found" on a record they just made.
Measuring: hit rate hides things
Hit rate is the headline metric, and it lies in two directions.
- A 99 % hit rate with a 1 % miss that costs 200 ms means the p99 of the endpoint is the database, not the cache. Track the latency distribution of hits and misses separately.
- Hit rate rises when you cache junk. Track hit rate per key class (user profiles, feed pages, config) and the eviction rate; evictions climbing while hit rate falls is the signal to add memory, not to add keys.
The other numbers to watch: memory used versus maxmemory, evicted keys per second, average key size, connection count, and (for Redis) the p99 of the slow log. A cache that is a single point of latency needs its own dashboard, because everything gets slower when it does.
When not to cache
- Data the user is about to act on where a stale read causes a wrong action: an inventory count at checkout, a balance before a transfer, a permission check after a revoke.
- Data with a read rate low enough that the cache never warms; you pay complexity and get misses.
- Data that is already cheap: a primary-key lookup on an index that is in the database's own buffer pool is already a sub-millisecond read.
Saying "we would not cache this, and here is why" is worth as much as adding a cache in the right place.
Checklist
- Which layer caches what, and the TTL on each.
- Read and write strategy, named (cache-aside plus write-around is the usual answer).
- Invalidation: TTL, explicit delete, or versioned key.
- Hot-key and stampede protection.
- Memory sizing from the working set, with the resulting hit rate and database load.
- What is deliberately not cached.
Questions people ask
What is caching in system design?
Caching stores the result of expensive work close to where it is needed, so the next request skips the work. It is the first tool for read scaling: with Zipfian reads over 100 M items at 50 k/s, caching the hottest 5 % yields roughly a 95 % hit rate and leaves the database 2.5 k/s. It is also the source of the most subtle bugs in distributed systems, which is why invalidation is always the follow-up question.
What is a look-aside cache?
A look-aside cache (cache-aside, or lazy loading) is one where the application checks the cache first and, on a miss, reads the database, writes the result to the cache and returns it. It is the default pattern because it only caches what is actually read and a cache failure degrades to the database. The costs are that the first read of every key is a miss, and stale data lives in the cache until the TTL expires or someone invalidates it.
Cache-aside vs write-through vs write-back: which should you use?
Cache-aside with write-around is the usual choice: write to the database, delete the cache key, and let the next read repopulate it. Write-through writes to the cache and the database synchronously, so reads after a write are always fresh, at the cost of write latency and caching data that may never be read. Write-back acknowledges once the cache has the write and flushes to the database in batches, so a counter incremented 10 k times becomes one database write, but a cache failure loses unflushed writes.
What are the layers of a caching architecture?
From the user inward, the layers are the browser, the CDN edge, an application cache such as Redis or Memcached, a local in-process cache, and the database's own cache of pages and index blocks. Each layer catches a share of requests so the next sees fewer. The browser caches static assets and API responses under Cache-Control and ETag, and an interview answer usually names two layers: a CDN for static and public content, and Redis for the application's hot working set.
What are the main caching challenges?
The hard problems are invalidation, hot keys and cache stampedes. A race between a reader and a writer can leave a stale value cached until the TTL, a single hot key can saturate one Redis shard (a node handles about 100 k to 1 M ops/s) while others idle, and a thundering herd hits the database when a hot key expires and thousands of requests miss at once. Typical fixes are versioned keys with short TTLs, replicating the hot key across shards, and request coalescing or stale-while-revalidate.
Redis vs Memcached: which is better for caching?
Redis is the safe default; choose Memcached for a pure large object cache. Memcached is a simple multithreaded key-value cache, slightly faster per node for plain get and set, that scales by adding nodes with client-side hashing. Redis adds data structures (lists, sorted sets, hashes, sets), pub/sub, Lua scripts, persistence, replication and a built-in cluster mode, so choose it whenever you need structure (leaderboards, rate limiting, queues) or persistence.