Updated 24 October 2026
Back-of-envelope estimation
The numbers to memorise for system design interviews (latency, throughput, storage, powers of two) and a repeatable method to estimate QPS, storage and bandwidth in under five minutes.
Try it yourself, in a playground:Queueing and Little’s lawShort code collisionsCache sizing
Estimation in an interview has one job: to find the part of the design that is under pressure. Nobody cares whether the answer is 40 k/s or 60 k/s. They care whether you noticed that 40 k reads/s at p99 under 50 ms cannot come from a relational database on disk.
The method
- Start from a given. Daily active users, or requests per day, or items created per day. If the interviewer will not give you one, propose one and say so.
- Convert to per-second. A day has 86 400 s; round it to 100 000 (10^5). So 10 M events/day is 100/s average.
- Apply a peak factor. Traffic is not flat. Use 2 to 3× for global consumer products, 5 to 10× for products with a daily rhythm (workplace tools, regional apps) or event spikes.
- Compute the dominant volume. Item size × items per day gives daily storage; multiply by 365 for a year, then by the retention period.
- Compute the pressured resource count. Connections, cache size, partitions, servers: divide the rate by a per-unit capacity you know.
- End with the implication. "Writes are not the problem; the read path is." "This is the single biggest stream in the system."
Round aggressively. Use powers of ten and keep one significant figure. Write intermediate results down so the interviewer can follow.
To check your arithmetic while you practice, the back-of-envelope estimator works the same steps from any set of givens and says what the numbers imply.
Numbers to memorise
Time
- 1 day ≈ 10^5 s (86 400). 1 month ≈ 2.6 M s. 1 year ≈ 3 × 10^7 s.
- 1 M requests/day ≈ 12/s. 100 M/day ≈ 1.2 k/s. 1 B/day ≈ 12 k/s.
Sizes
| Unit | Bytes | Fits |
|---|---|---|
| 1 KB | 10^3 | a tweet with metadata, a small JSON record |
| 1 MB | 10^6 | a high-resolution photo (compressed), a minute of MP3 |
| 1 GB | 10^9 | an hour of 1080p video, a small relational database |
| 1 TB | 10^12 | one modern SSD, a year of logs for a mid-size service |
| 1 PB | 10^15 | a large data warehouse |
A UUID is 16 bytes, a 64-bit id is 8 bytes, a timestamp is 8 bytes, a short string is 20 to 100 bytes. A typical row with a dozen fields is 200 B to 1 KB before indexes; double it for indexes and replication overhead.
Latency
| Operation | Time |
|---|---|
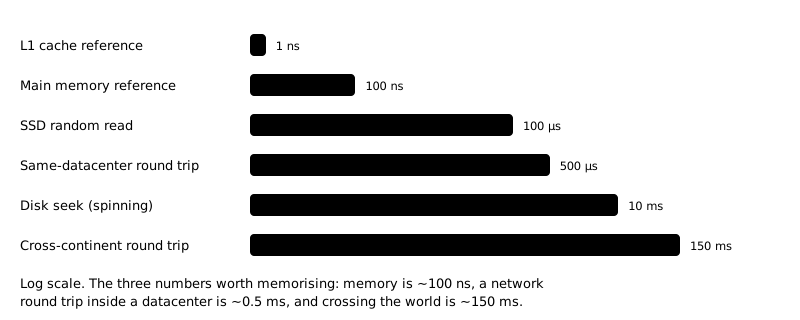
| L1 cache reference | 1 ns |
| Main memory reference | 100 ns |
| Read 1 MB sequentially from memory | 10 µs |
| SSD random read | 100 µs |
| Read 1 MB from SSD | 1 ms |
| Round trip inside a data center | 0.5 ms |
| Read 1 MB from spinning disk | 20 ms |
| Round trip across a continent | 50 to 100 ms |
| Round trip across the world | 150 to 300 ms |
The lessons: memory is 1000× faster than SSD, which is 10× faster than disk; a network hop inside a region costs about as much as an SSD read; a cross-region hop costs as much as 100 SSD reads. A p99 budget of 100 ms allows one cross-region call or a few dozen intra-region calls, not both.
Throughput per node
These are rough capacities for one well-configured server. Use them to convert a rate into a count of machines.
| Component | Capacity |
|---|---|
| Stateless HTTP service | 5 k to 20 k requests/s per instance |
| Relational database (Postgres, MySQL) | 5 k to 20 k simple queries/s; 1 k to 5 k writes/s |
| Redis / Memcached | 100 k to 1 M ops/s |
| Kafka partition | 10 MB/s or ~10 k messages/s; a broker handles hundreds of partitions |
| Cassandra / DynamoDB node | 10 k to 50 k ops/s |
| WebSocket connections | 100 k to 1 M idle connections per server (memory-bound) |
| Elasticsearch | 1 k to 10 k queries/s per node depending on query |
| Network | 10 to 25 Gbit/s per server (1 to 3 GB/s) |
Availability
| Target | Downtime per year | Per month |
|---|---|---|
| 99 % | 3.65 days | 7.3 hours |
| 99.9 % | 8.8 hours | 44 minutes |
| 99.99 % | 53 minutes | 4.4 minutes |
| 99.999 % | 5.3 minutes | 26 seconds |
Availability multiplies through dependencies: a request that needs three 99.9 % services is at most 99.7 % available. Parallel redundancy adds nines: two independent 99 % replicas give 99.99 %.
Worked example: a Twitter-like feed
Given 300 M DAU, each posts 0.5 tweets per day and reads 50.
- Writes: 150 M/day ÷ 10^5 ≈ 1.5 k/s average, ~5 k/s peak. Trivial for any store.
- Reads: 15 B/day ≈ 150 k/s average, ~500 k/s peak. Not trivial; this is the pressured path.
- Fan-out: average 200 followers, so 1.5 k tweets/s becomes 300 k feed inserts/s. Larger than the read rate. This is the number that decides fan-out-on-write versus fan-out-on-read.
- Storage: a tweet is ~300 B with metadata; 150 M × 300 B = 45 GB/day, ~16 TB/year. Media dominates: if 10 % carry a 200 KB image, that is 3 TB/day.
- Cache: the feed cache holds the last 500 ids per active user: 300 M × 500 × 8 B = 1.2 TB. Fits across a modest Redis cluster; that confirms fan-out-on-write is affordable for ordinary users.
The final sentence: "Reads and fan-out dominate. Precompute feeds for normal users, but a celebrity with 50 M followers cannot be fanned out on write, so hybrid."
Common mistakes
- Estimating storage to three decimal places while ignoring the read rate.
- Forgetting the peak factor, then designing for average.
- Forgetting replication (×3) and indexes (×2) when sizing storage.
- Multiplying without writing down the intermediate result, then losing the thread when the interviewer interrupts.
- Not saying what the number means. Every estimate should end in a design decision.
Unit discipline
Most estimation mistakes are unit mistakes, not arithmetic mistakes. Two habits fix almost all of them:
- Write the unit next to every number, including intermediates:
40 msg/user/day × 10 M user = 400 M msg/day. If the units on both sides do not cancel to what you want, you have a bug. - Round to one significant figure and use powers of ten.
86 400is10^5.1.2 k/sis fine;1 157/sis false precision and slows you down.
Keep the per-second conversion in your head as a single step: per day ÷ 10^5 = per second, then multiply by the peak factor.
Sanity checks that catch errors
Before you use a number, test it against something you know:
- Per-user check. Divide by the user count. 400 M messages/day over 10 M DAU is 40 per user: plausible. If it comes out at 4 000, something is wrong.
- Per-machine check. Divide by a machine's capacity. A modern server handles roughly 10–50 k simple requests/s, holds 25–50 k idle connections, and a database instance takes maybe 10 k writes/s. If your design needs 4 servers for 1 M req/s, redo it.
- Bandwidth check. Multiply request rate by payload size. 100 k/s × 10 KB is
1 GB/s= 8 Gbps, which is a real network constraint worth mentioning. - Money check. Order-of-magnitude cost: petabytes of hot storage and terabytes of egress are the line items that dominate media products.
Cost, in one line each
Interviewers increasingly ask "what does this cost?" Rough public-cloud order of magnitude, enough to compare designs:
- Object storage: ~$20 per TB per month hot, ~$1–4 per TB archive.
- Egress to the internet: ~$50–90 per TB, usually the largest bill in a media system, and the reason CDN hit rate is a business metric.
- A general-purpose VM: ~$50–100 per month for a small one, ~$500–1 000 for a large one.
- Managed database: roughly 2–3× the raw VM cost for the same resources.
Use them for ratios, not for a quote: "serving is 10× the storage cost, so caching at the edge is the lever" is the kind of sentence that lands.
Questions people ask
What is a back of the envelope calculation in system design?
A back of the envelope calculation is a rough estimate of QPS, storage and bandwidth, made in a few minutes, to find the part of the design that is under pressure. The exact figure does not matter: nobody cares whether the answer is 40 k/s or 60 k/s. What matters is noticing, for example, that 40 k reads/s at p99 under 50 ms cannot come from a relational database on disk.
How do you calculate QPS in system design?
Divide the daily count by 10^5 to get the average per second, then multiply by a peak factor. A day has 86 400 seconds, which rounds to 10^5, so 10 M events a day is about 100/s on average. Then apply a peak factor: 2 to 3× for global consumer products, 5 to 10× for products with a daily rhythm (workplace tools, regional apps) or event spikes. Forgetting the peak factor and designing for the average is a common mistake.
How do you do a back of the envelope estimation step by step?
Start from a given such as daily active users, convert it to per second, apply a peak factor, compute the dominant volume, count the pressured resource, and end with what the number implies for the design. Round to one significant figure, use powers of ten and write intermediate results down. For example, 300 M daily users each reading 50 posts is 15 B reads a day, about 150 k/s on average and roughly 500 k/s at peak.
What numbers should you memorise for a system design interview?
Memorise time conversions, a few latencies and per-node throughput, since they turn a rate into a count of machines and show what fits in a latency budget. A day is about 10^5 seconds, so 1 M requests a day is about 12/s. Three latencies carry most interviews: about 100 ns for memory, 0.5 ms for a round trip inside a data center and 150 ms across the world. A stateless HTTP service handles 5 k to 20 k requests/s per instance.
How do you estimate storage in system design?
Multiply item size by items per day for daily storage, then by 365 for a year and by the retention period. Then allow for replication (×3) and indexes (×2), which are commonly forgotten when sizing storage. For example, 150 M tweets a day at about 300 B each is 45 GB a day, roughly 16 TB a year, and if 10 % carry a 200 KB image, media adds 3 TB a day.
How do you check a back of the envelope estimate?
Test each number against something you already know: divide by the user count, divide by a machine's capacity, and multiply the request rate by the payload size. If 400 M messages a day over 10 M daily users comes out at 40 per user, it is plausible; 4 000 per user would mean something is wrong. Likewise, 100 k requests/s at 10 KB each is 1 GB/s, or 8 Gbps, which is a real network constraint worth mentioning.