Updated 24 October 2026
Message queues and event streams
When to go asynchronous, queues vs logs (SQS, RabbitMQ vs Kafka), delivery guarantees, ordering, consumer groups, dead-letter queues, backpressure, and the outbox pattern.
Try it yourself, in a playground:Kafka partitions and consumer groupsDelivery semanticsMessage orderingDead-letter queuesLog compactionPriority queuesConsumer rebalancing
A queue lets one part of the system hand work to another without waiting for it. That single property buys you decoupling (the producer does not know or care who consumes), buffering (a burst is absorbed and drained at the consumer's pace), and resilience (a consumer outage delays work instead of failing requests). Nearly every design has an asynchronous path, and interviewers ask three things about it: what goes through it, what happens when a message is delivered twice, and what happens when consumers fall behind.
What to make asynchronous
Anything the user does not need to see in the response: sending email and push notifications, resizing images, updating search indexes and caches, fanning out a post to followers, writing analytics, calling slow third parties, and any retryable side effect. The rule: if the request can return success before this work is done, and the work can be retried safely, it goes on a queue.
Keep synchronous: the write to the system of record, authorisation, anything the user must see immediately (their own message in the chat), and anything whose failure must fail the request (payment authorisation).
Queues versus logs
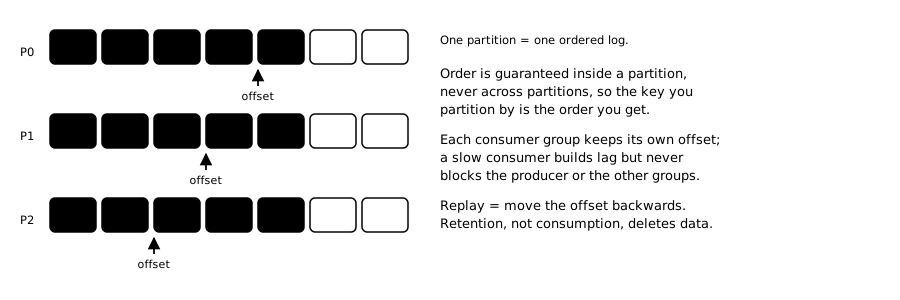
Queues (SQS, RabbitMQ, Google Pub/Sub in its default mode) deliver each message to one consumer and delete it when acknowledged. They model tasks: each message is a job to be done once. Good for work distribution, retries with visibility timeouts, and priority. No replay: once consumed, it is gone.
Logs (Kafka, Pulsar, Kinesis, Redpanda) append messages to a partitioned, ordered, durable log that consumers read at their own offset. Messages are retained for a period (days to forever) regardless of consumption. Many independent consumer groups can read the same stream; a consumer can rewind and replay. They model events: things that happened, which several systems want to know about. Higher throughput (millions of messages per second per cluster) and ordering per partition.
Choose a queue for jobs with one consumer; choose a log when multiple consumers need the same events, when replay matters (rebuilding a cache or index), or when order within a key matters. In interviews, "Kafka" is the default for event streams and "SQS" for job queues, and it is fine to say both are in the design.
Delivery guarantees
- At most once. Fire and forget. Messages can be lost. Acceptable only for metrics and similar.
- At least once. The broker redelivers until acknowledged; consumers must handle duplicates. This is what every practical system provides.
- Exactly once. Not achievable end to end across arbitrary systems. Kafka offers exactly-once within a Kafka-to-Kafka pipeline via transactions, and some sinks support it via idempotent writes. In practice "exactly once" means at-least-once delivery plus idempotent processing.
So the real question is how the consumer is idempotent: a unique message id checked against a processed set (a table or Redis set with TTL), a natural idempotency key (the order id for "send confirmation"), or an idempotent operation (set status = shipped, not increment count). See idempotency.
Ordering
A queue does not guarantee order in general; a log guarantees order within a partition. Choose the partition key so that everything that must be ordered shares a key: user id, channel id, order id. Then the events for one order arrive in order, while different orders are processed in parallel. Ordering across keys is not needed and not worth the cost. If the interviewer asks about global ordering, the answer is "one partition, and it will not scale; instead I make consumers tolerant of reordering across keys".
Consumers and scaling
A consumer group shares a topic: each partition is read by exactly one consumer in the group. Parallelism is therefore bounded by partition count; choose it generously up front (partitions are cheap, resharding is not) and aim for 10 to 100 per topic. Each consumer commits its offset after processing; a crash means the next consumer replays from the last commit, which is where duplicates come from.
Backpressure is what happens when producers outrun consumers. With a log, the lag grows (offset distance) and retention protects you for days; monitor consumer lag and autoscale consumers up to the partition count. With a queue, the queue depth grows; set alarms on depth and age of oldest message. If consumers cannot catch up, you either add partitions and consumers, batch the work, or shed load by dropping low-priority messages.
Failure handling
- Retries. A failed message is retried with exponential backoff. Distinguish transient failures (retry) from permanent ones (bad data: do not retry forever).
- Dead-letter queue. After N failures, move the message aside for inspection so one poison message does not block the partition. Alert on DLQ depth.
- Visibility timeout. With SQS-style queues, a message being processed is hidden for a timeout; if the consumer crashes, it reappears. Set the timeout longer than processing time or you get duplicates under normal operation.
- Idempotent consumers are the answer to all of the above.
The outbox pattern
The subtle bug: a service writes to its database and then publishes an event, and crashes in between. The database has the order; the stream does not. Or the publish succeeds and the commit fails. Dual writes to two systems cannot be atomic.
The fix is the transactional outbox: write the event to an outbox table in the same database transaction as the business change. A separate relay reads the outbox (polling or via CDC) and publishes to the stream, marking rows sent. Publishing is at-least-once, so consumers are idempotent. This pattern comes up in every payments, ordering and messaging design; say it unprompted.
The alternative is change data capture: skip the outbox and publish the database's own change log (Debezium). Less code, but the event schema is your table schema.
Sizing
Kafka: a partition handles roughly 10 MB/s and tens of thousands of messages per second; a broker handles thousands of partitions; a modest 6-broker cluster does a million messages per second. Retention is a disk calculation: 100 k msgs/s × 1 KB × 7 days ≈ 60 TB with replication factor 3 (before compression). SQS is effectively unlimited with a per-queue throughput in the thousands per second and no retention beyond 14 days.
In the interview
"After committing the message to the store, the service writes an event to an outbox table in the same transaction; a relay publishes it to Kafka keyed by channel id, so a channel's events stay ordered. Fan-out workers in a consumer group read it and push to connected clients; a second consumer group updates the search index. Consumers are idempotent on message id. Lag is monitored and consumers scale to the partition count; poison messages go to a DLQ after three retries."
Backpressure and lag
Consumer lag (how far behind the head of the log a consumer is, in events and in seconds) is the health metric for everything asynchronous. Alert on time lag rather than message count, because message count means nothing without the rate.
When a consumer cannot keep up, the options in order of preference:
- Add partitions and consumers. Only works if the key distribution spreads; more consumers than partitions do nothing.
- Batch harder. Write 500 rows in one statement instead of 500 statements; most consumers are sink-bound, not CPU-bound.
- Shed or degrade. Drop low-value events (analytics pings) to protect high-value ones, which is an argument for separate topics by priority.
- Slow the producer. Only when the producer is internal. On a user-facing path, this becomes 429s and a queue is no longer decoupling anything.
The failure to name is the one that cascades: a consumer that retries in a tight loop against a failing sink turns a downstream outage into a broker outage.
Schema evolution
Events outlive the code that wrote them, because they sit in the log for days and in cold storage forever.
- Version every event type and add fields, never repurpose or remove them; consumers ignore unknown fields.
- Use a schema registry with compatibility checks (backward compatible by default) so a producer cannot ship a breaking change.
- Deploy consumers before producers when adding a field consumers must understand.
- Keep a dead-letter path for events that fail to parse; silent drops on a schema mismatch are the classic incident.
Choosing a broker
| Need | Reasonable answer |
|---|---|
| Ordered, replayable, high throughput, multiple independent consumers | Kafka (or Pulsar, Kinesis) |
| Task queue with per-message ack, retries, visibility timeouts | SQS, RabbitMQ, or a database-backed queue |
| Fan-out to many subscribers, no retention | SNS, Redis pub/sub |
| Scheduled or delayed work | a queue with delayed delivery, or a table with a due-at index |
| Small scale, no new infrastructure | a table with SELECT … FOR UPDATE SKIP LOCKED |
The last row is a real answer and worth saying: at a few hundred jobs per second, a Postgres-backed queue is simpler and easier to reason about than a broker.
Checklist
- What is asynchronous, and what the user sees while it is pending.
- Queue or log, and the retention.
- Delivery guarantee, plus where idempotency is enforced.
- Partition key and the ordering it buys.
- Retry policy, DLQ, and who looks at the DLQ.
- Lag metric and its alert threshold.
Questions people ask
What is a message queue?
A message queue lets one part of a system hand work to another without waiting for it, delivering each message to one consumer and deleting it when acknowledged. That buys decoupling (the producer does not know who consumes), buffering (a burst is drained at the consumer's pace) and resilience (a consumer outage delays work instead of failing requests). SQS and RabbitMQ work this way, and there is no replay: once a message is consumed, it is gone.
Message queue vs event stream: what is the difference?
A message queue deletes each message once one consumer acknowledges it, while an event stream is a partitioned, ordered, durable log that keeps messages for a retention period regardless of consumption. Queues model tasks to be done once; streams model events that several systems want to know about, and each consumer group reads at its own offset and can rewind to replay. Streams also give higher throughput (millions of messages per second per cluster) and ordering within a partition.
When should you use an event stream instead of a message queue?
Use an event stream when several consumers need the same events, when replay matters (rebuilding a cache or an index), or when order within a key matters; use a message queue for jobs that one consumer does once. In interviews Kafka is the default for event streams and SQS for job queues, and a design can have both. At a few hundred jobs per second, a Postgres table read with SELECT … FOR UPDATE SKIP LOCKED is simpler than a broker.
When should you use a message queue in system design?
Use a message queue for work the user does not need to see in the response and that can be retried safely: if the request can return success before the work is done, it goes on a queue. Typical examples are sending email and push notifications, resizing images, updating search indexes and caches, fanning out posts to followers and writing analytics. The write to the system of record, authorisation and anything whose failure must fail the request (payment authorisation) stay synchronous.
Can a message queue guarantee exactly-once delivery?
No: exactly-once delivery is not achievable end to end across arbitrary systems, although Kafka offers it within a Kafka-to-Kafka pipeline via transactions. Every practical system provides at-least-once delivery, so in practice exactly once means at-least-once delivery plus idempotent processing. The consumer can check a unique message id against a processed set, use a natural idempotency key such as the order id, or apply an idempotent operation (set status to shipped, rather than increment a count).