Updated 24 October 2026
Unique ids, ordering and time
Auto-increment vs UUID vs Snowflake vs ULID/UUIDv7, time-ordered ids, id generation at scale, clock skew, logical clocks, and why "ordered by time" is harder than it sounds.
Try it yourself, in a playground:Snowflake IDsB-tree indexShort code collisionsClock skew and logical clocksUUID primary keys
Every design needs ids, and the choice shapes sharding, sorting, pagination and URL enumerability. Interviewers ask "how do you generate ids" when there are multiple writers, and "how do you order messages" when clocks are involved. Both have standard answers with known tradeoffs.
What you want from an id
- Unique across all writers without coordination on the hot path.
- Sortable by creation time, so that a range scan by id is a range scan by time and pagination cursors are just ids.
- Compact: 64 bits indexes and stores far better than 128, and much better than a string.
- Non-enumerable when exposed publicly: sequential ids leak volume and let anyone iterate every record.
No scheme gives all four; pick by which matter.
The options
Auto-increment. The database assigns the next integer. Compact, sortable, simple, and the right choice for a single-primary relational database. It fails with multiple writers (two primaries assign the same id) and leaks volume publicly. Workaround for multi-primary: offset and step (server 1 assigns odd, server 2 even), which does not scale past a fixed count.
UUID v4. 128 random bits, generated anywhere with no coordination. Unique in practice, non-enumerable, but random: as a primary key it fragments B-tree indexes (each insert lands at a random page), doubles index size versus 64 bits, and cannot be sorted by time.
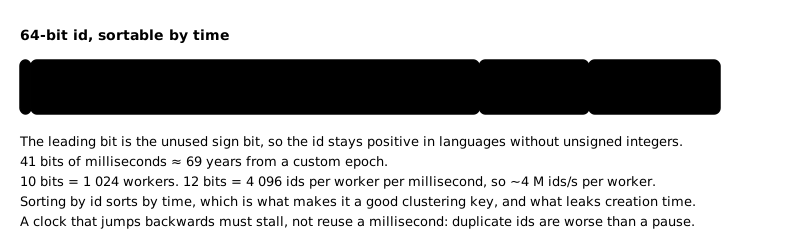
Snowflake. A 64-bit id: 41 bits of milliseconds since a custom epoch, 10 bits of worker id, 12 bits of per-millisecond sequence. Time-ordered, compact, generated locally at 4096 per millisecond per worker with no coordination once the worker id is assigned (from ZooKeeper, etcd, or a config). Twitter, Discord and Instagram use variants. The catch is clock dependence: a worker whose clock goes backwards must refuse to generate until it catches up, and ids from different workers within the same millisecond are ordered by worker, not by true time.
ULID and UUID v7. 128-bit ids with a 48-bit millisecond timestamp prefix and random bits after it. Time-ordered like Snowflake, coordination-free like UUID v4 (no worker id to assign), and index-friendly because inserts are monotonic. The cost is 128 bits. UUID v7 is now standardised and supported natively by Postgres 17+; it is the modern default for new systems that do not want to run a worker-id registry.
Ticket server / ranged counters. A tiny highly available service hands out ranges of ids (1000 at a time) from a database counter; each application instance uses its range locally. Compact and sequential, one coordination call per thousand ids, and the counter is a single point that must be replicated. Flickr ran this way; URL shorteners use it with a bijective scramble to base62 to make codes non-enumerable. See Design a URL Shortener.
Hash of content. sha256(content) as the id. Deduplicates identical content automatically (object storage, content-addressable systems), not sortable, deterministic.
Choosing
| Need | Choice |
|---|---|
| Single Postgres, internal ids | bigint auto-increment; expose a separate public id |
| Distributed writers, time ordering, compact | Snowflake |
| Distributed writers, no infra, index-friendly | UUID v7 / ULID |
| Public, must not be enumerable | UUID v4/v7 or a scrambled counter |
| Short human-typed code | ranged counter + base62 scramble |
| Deduplicating blobs | content hash |
Ordering by time is not simple
Time-ordered ids order events by the generating node's clock, and clocks disagree. NTP-synced servers typically differ by a few milliseconds and occasionally much more (a VM pause, a leap second). Two consequences to know:
- Two messages in one channel from different servers can get ids out of true order if their clocks differ. For most products this is invisible (milliseconds). Where order must be exact within a key (messages in a channel, events for an order), assign ids on a single writer per key: route all writes for channel X to one partition or use the database's own sequence per partition. Then the id is a true sequence within the key, and cross-key ordering does not matter.
- Never use wall-clock timestamps to decide conflicts (last-writer-wins by timestamp) unless you accept that a fast clock always wins. Use versions or vector clocks where it matters.
Logical clocks. A Lamport clock is a counter each node increments on every event and updates to max(local, received) + 1 on every message; it gives an order consistent with causality (if A caused B, A's stamp is smaller) without any wall clock. Vector clocks (one counter per node) additionally detect concurrent updates, which is how Dynamo-style stores know two versions conflict. Hybrid logical clocks (used by CockroachDB) combine wall time with a logical counter so timestamps are close to real time and still causally consistent. Mention Lamport clocks if the interviewer pushes on ordering; you rarely need to design one.
TrueTime. Google Spanner uses GPS and atomic clocks to bound clock uncertainty to a few milliseconds and waits out the uncertainty before committing, giving globally consistent timestamps. The point to make: strict global time ordering is possible but costs a commit-wait, and almost no product needs it.
Cursor pagination with ids
Time-ordered ids make pagination trivial and stable: WHERE id < :last_seen ORDER BY id DESC LIMIT 50. The cursor is the last id, opaque to the client, and inserts do not shift the pages. This is the single biggest practical reason to prefer time-ordered ids for anything listed in time order.
Generating ids for a URL shortener or invite code
Short codes need a small space, so a 64-bit id is too long. Take a counter (from a ranged ticket server), apply a bijective scramble (multiply by a large odd constant mod 2^k, or a Feistel network) so consecutive counters produce unrelated codes, and encode in base62 to 7 characters. Uniqueness comes from the counter, unpredictability from the scramble, and there is no collision check on the hot path.
In the interview
"Message ids are Snowflake-style 64-bit: 41 bits of time, 10 bits of worker, 12 bits of sequence, generated on the message service with worker ids leased from etcd. They are time-ordered so history is a range scan and the client's cursor is just the last id. Within a channel, all writes go through one partition so the order is exact; across channels, millisecond clock skew is acceptable. Public ids are the same value base62-encoded."
Clocks: what you can and cannot assume
- Wall-clock time (
System.currentTimeMillis,time.time()) can jump backwards when NTP corrects drift. Never measure an elapsed duration with it, and never assume two machines agree. - Monotonic clocks only move forward and are the right tool for timeouts, latency measurement and lease expiry.
- NTP typically keeps machines within a few milliseconds in a datacenter and tens of milliseconds across the internet. Design as though the skew is 100 ms and you will rarely be wrong.
- TrueTime (Spanner) is the exception: GPS and atomic clocks give a bounded uncertainty interval, and the database waits out the uncertainty to make timestamps globally meaningful. Naming it is a good way to answer "how could you get globally consistent ordering" honestly: you buy it with hardware and a commit wait.
- Hybrid logical clocks are the practical middle ground: a physical timestamp plus a logical counter, so causally related events order correctly even when clocks disagree slightly. This is what many distributed databases use internally.
The interview sentence: "I would not rely on clock ordering across machines. For causality I would use a logical clock or the log's own order; wall-clock time is for humans and for approximate bucketing."
Checklist
- The id scheme, and whether it is sortable, guessable and how large.
- Where ids are generated: client, service, or a dedicated generator.
- What happens on clock skew or a worker id collision.
- Whether the id leaks creation time or volume, and whether that matters.
- The cursor format for pagination, and what happens to a cursor when the row is deleted.
Questions people ask
How do you generate unique IDs in a distributed system?
Use a scheme that each writer can generate without coordination on the hot path: Snowflake ids for compact, time-ordered 64-bit ids, or UUID v7 or ULID when you want no infrastructure to run. Auto-increment suits a single-primary relational database but fails with multiple writers, because two primaries assign the same id. A ticket server that hands out ranges of 1000 ids from a database counter is another option, with one coordination call per thousand ids.
What is a Snowflake ID?
A Snowflake id is a 64-bit id made of 41 bits of milliseconds since a custom epoch, 10 bits of worker id and 12 bits of per-millisecond sequence, and Twitter, Discord and Instagram use variants. Time in the high bits makes it sortable by creation time, and each worker generates up to 4096 ids per millisecond with no coordination once its worker id is assigned. The catch is clock dependence: a worker whose clock goes backwards must refuse to generate ids until it catches up.
UUID vs sequential ID: which is better as a primary key?
A sequential auto-increment id is compact, sortable and simple, but fails with multiple writers and leaks volume publicly. A random UUID v4 can be generated anywhere and is non-enumerable, but as a primary key it fragments B-tree indexes, doubles index size versus 64 bits, and cannot be sorted by time. UUID v7 and ULID sit between them: time-ordered and index-friendly because inserts are monotonic, coordination-free like UUID v4, at the cost of 128 bits.
Snowflake ID vs UUID v7: which should you use?
Use Snowflake when you want compact 64-bit, time-ordered ids from distributed writers and can assign worker ids, and UUID v7 when you want time ordering with no infrastructure. Both are sortable by creation time and generated locally. UUID v7 costs 128 bits but needs no worker id, which makes it the modern default for new systems that do not want to run a worker-id registry; Postgres 17+ supports it natively.
Do time-ordered IDs guarantee order across servers?
No, because time-ordered ids order events by the generating node's clock, and clocks disagree. NTP-synced servers typically differ by a few milliseconds and occasionally much more, so two messages in one channel from different servers can get ids out of true order. Where order must be exact within a key, such as messages in a channel, route all writes for that key to one partition, so the id is a true sequence within the key.
Why use time-ordered IDs for pagination?
Time-ordered ids make cursor pagination trivial and stable, because the cursor is just the last id seen. The query is WHERE id < :last_seen ORDER BY id DESC LIMIT 50, the cursor is opaque to the client, and new inserts do not shift the pages. This is the single biggest practical reason to prefer time-ordered ids for anything listed in time order.